


Most guides on how to choose a business intelligence tool rank vendors by feature count, connector lists, and pricing tiers. Those comparisons are useful, but they say little about what happens when your architecture, pricing, ownership structure, or reporting requirements change. The question that matters more than any feature matrix is blunt: if you cancel this contract tomorrow, what leaves with you?
Key Takeaways
- Test portability before features: a BI tool’s long-term value depends on whether your data models, metric definitions, and dashboards can move to another platform intact.
- Keep analytical data in an independent storage layer using open formats rather than the BI vendor’s proprietary warehouse ↗.
- Require documented export paths for data, metadata, semantic models, dashboards, and row-level-security rules before signing any BI contract.
- Place reusable metric definitions in a separately governed semantic layer so business logic is not trapped inside one reporting tool ↗.
- Evaluate multi-cloud and on-premises connectivity: a tool that only reads from one ecosystem narrows your future options ↗.
- In a proof of concept, measure migration cost in person-days and recorded defects, not only in a vendor’s self-assigned "open" label.
- Separate transformation logic from the visualization tool and store transformation code in version control for maximum replaceability.
Where a takeaway carries an ↗ link, that page supports it. The other recommendations are Veralytiq’s own evaluation framework, not requirements stated in vendor documentation.
Table of Contents
- What does "locked in" actually mean in a BI stack?
- A five-test framework to evaluate any business intelligence tool for portability
- How to estimate migration cost before you sign
- Why 2026 changes the math: Open Semantic Interchange and AI execution layers
- Contract and procurement levers most buyers forget
- SMB vs. enterprise: a different path to the same protections
- Choose the business intelligence tool that makes leaving cheap
What does "locked in" actually mean in a BI stack?
Lock-in is not a single trap: it is a set of quiet dependencies that accumulate across data storage, business logic, dashboards, embedded analytics, and user skills. Most organizations only discover the full scope when they try to leave.
Consider a mid-sized company that adopted a BI platform three years ago. The dashboards work. Users are trained. Monthly reports reach the executive team on schedule. Then a strategic shift (a cloud migration, an acquisition, a cost review) makes the current platform untenable. What happens next is where lock-in becomes visible.
The data itself might sit in a proprietary warehouse the BI vendor controls. The metric definitions ("net revenue," "active customer," "on-time delivery rate") live inside the tool’s semantic model, written in a proprietary expression language. Dashboards reference those definitions through internal object IDs, not through portable SQL. Row-level security rules map to the vendor’s identity model. Embedded analytics in customer-facing applications depend on vendor-specific SDKs and JavaScript libraries.
A vendor may advertise interoperability mechanisms. Microsoft’s Power BI documentation, for instance, identifies XMLA, REST APIs, TOM, TMDL, Delta Lake, Parquet, and Iceberg as interoperability features, but these do not make every report or calculation portable ↗. The gap between "we expose an API" and "you can reconstruct your entire BI environment elsewhere" is where migration budgets go to die.
A common mistake is equating connector count with low lock-in, because a platform may connect to many sources while still trapping metric definitions, access policies, refresh schedules, and dashboard layouts in proprietary metadata. Another misconception: that an open file format automatically makes a BI deployment portable, because Parquet, Delta Lake, or Iceberg may preserve data storage while leaving calculations, security semantics, and presentation logic behind.
If you are evaluating BI tools for a manufacturing analytics stack or a logistics control tower, the dependency web is often deeper than it appears, because operational data frequently involves complex refresh pipelines and embedded views that front-line teams rely on daily.
So lock-in is not a binary state. It is a spectrum, and the only way to measure where you sit on it is to test what actually survives a move.
A five-test framework to evaluate any business intelligence tool for portability
Apply these five tests to any business intelligence tool before you commit: they separate genuine openness from marketing claims about openness.
Test 1: Is your data in an independent storage layer?
Keep analytical data in an independent storage layer rather than the BI vendor’s proprietary warehouse. Microsoft states that Power BI’s Direct Lake mode uses open storage formats including Delta Lake, Parquet, and Apache Iceberg, which can reduce dependence on proprietary storage formats ↗. The operative word is "can." You still need to verify that the data your organization actually queries, not just the raw files, is accessible without the BI tool running.
Test 2: Do metric definitions live in a governed semantic layer?
MIT’s Center for Information Systems Research defines a semantic layer as technology that maintains a consistent, unified representation of data from multiple sources that humans and machines can interpret ↗. If your "net revenue" calculation exists only inside a vendor’s proprietary expression language, you will rewrite it during migration. If it exists in a semantic layer that other tools can query, you won’t.
Test 3: Can external applications call the metrics through a documented protocol?
Use SQL, REST, or another documented protocol as an exit interface, because an interface that external applications can call is easier to test and replace than logic available only inside a closed report authoring environment ↗. Ask whether a Python script, a downstream application, or an AI agent can retrieve a metric value without opening the BI tool’s native UI.
Test 4: Is transformation logic stored outside the visualization tool?
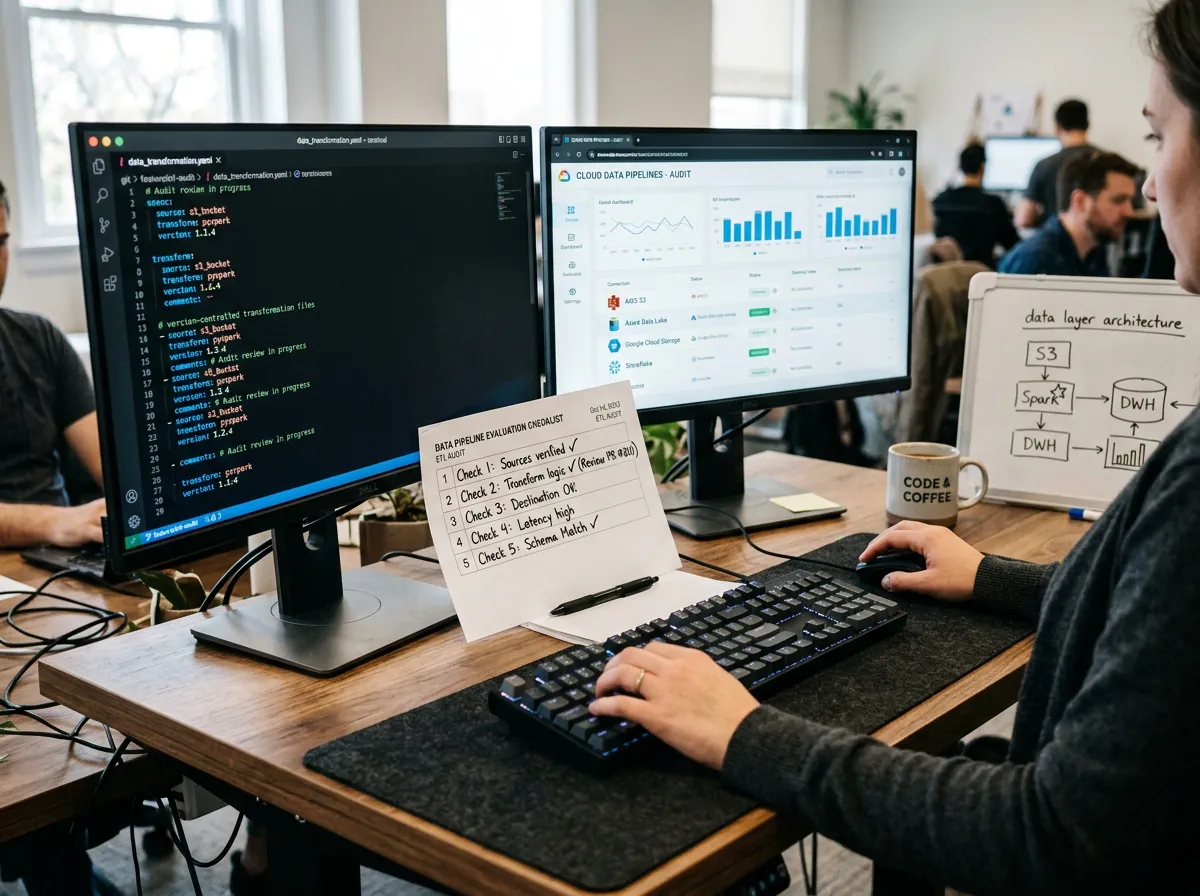
A BI platform that consumes warehouse tables or views produced by independently managed pipelines gives an organization more replacement options than a platform that embeds joins, filters, and business rules inside hundreds of unpublished reports. Separate transformation logic from the visualization tool and store transformation code in version control. This discipline can reduce migration effort by keeping transformation logic independent of the visualization layer.
Test 5: Does the tool connect to more than one cloud and on-premises platform?
Qlik states that its platform can connect to AWS, Microsoft Azure, Google Cloud Platform, Snowflake, and legacy on-premises systems, although vendor claims about connector breadth should be validated against the specific source systems used by an organization ↗. The test is not "how many connectors does the marketing page list?" but "can I point this tool at the three data platforms we actually use today and the one we might use next year?"
Organizations building a retail BI stack or evaluating BI for professional services should run all five tests against their specific data sources and report catalog, not against a vendor demo environment.
How to estimate migration cost before you sign
The following worksheet is a Veralytiq evaluation framework. The referenced product documentation confirms which technical interfaces exist; the recommended testing and measurement process is our practical interpretation of how buyers should evaluate them.
The time to estimate migration cost is before you sign the contract, not when you are already trying to leave.
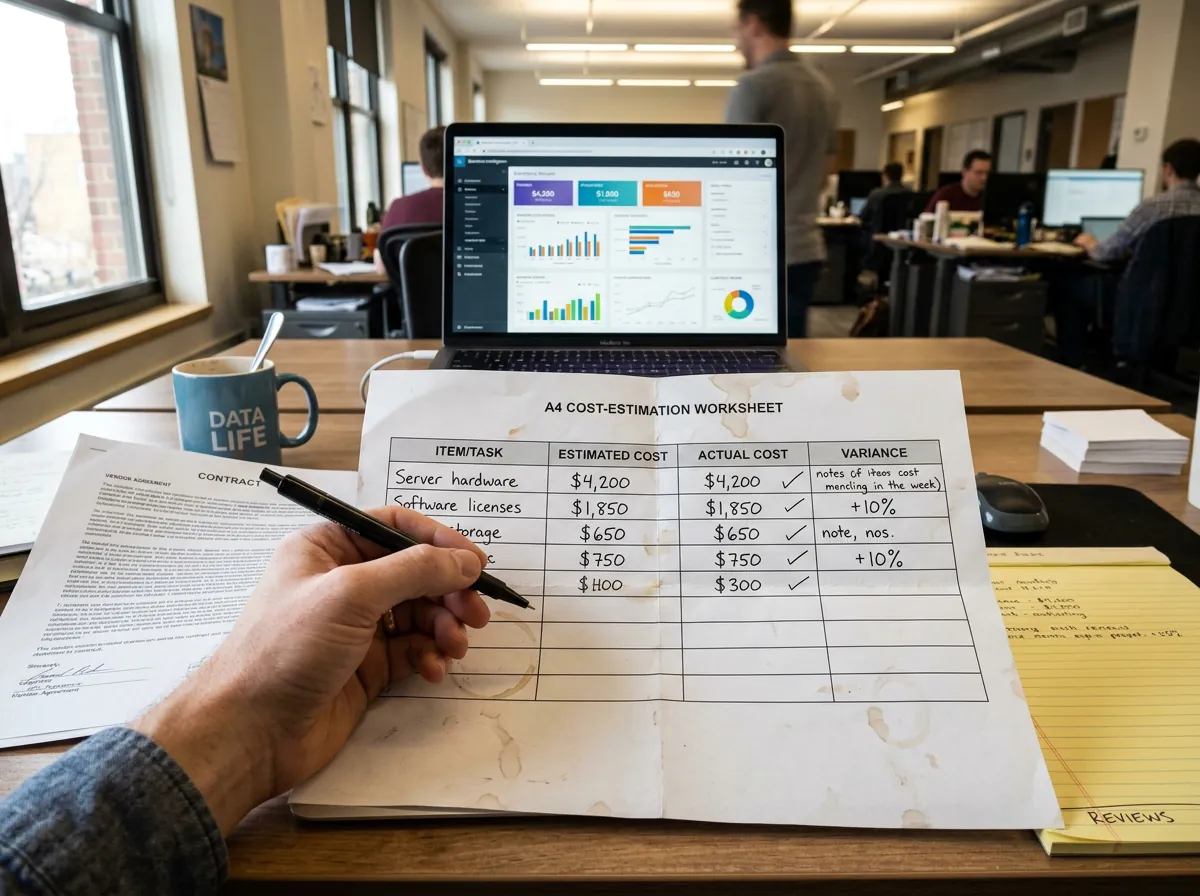
Require documented export paths for data, metadata, semantic models, dashboards, and row-level-security rules before signing a BI contract. Microsoft documents Power BI automation through Fabric REST endpoints, the XMLA endpoint, Tabular Object Model, and Tabular Model Definition Language ↗. That documentation is a starting point, not a guarantee.
A practical way to estimate migration cost is to build a worksheet with four cost buckets:
Bucket 1: Proprietary code rewrite. Count every DAX measure, every custom visual, every calculated column that uses a vendor-specific language. Each one needs a rewrite in the target platform’s language. Multiply the count by an estimated rewrite time per object.
Bucket 2: Hidden dependencies. Identify every refresh schedule, incremental-refresh pipeline, and row-level-security model. These rarely export cleanly. Run a migration proof of concept using representative reports rather than relying on feature checklists. For a practical migration proof of concept, Veralytiq recommends selecting reports that exercise different platform dependencies. A representative set can include a row-level-security model, an incremental-refresh pipeline, a complex time-intelligence calculation, an embedded dashboard, and an executive report with external distribution.
Bucket 3: Export gaps. For each artifact category (dashboards, alerts, subscriptions, usage logs), confirm whether a documented export path exists. A technically documented export function is not equivalent to a contractual right to retrieve every relevant artifact at termination.
Bucket 4: Retraining hours. Every user who knows the current tool’s interface will need time on the new one. This cost is real and often underestimated.
As part of your proof of concept, we recommend measuring migration effort in person-days and recording defects or unsupported artifacts instead of relying only on a vendor’s “open” or “interoperable” label. The total across all four buckets is your switching cost. If that number is high, the vendor has leverage over you for the life of the contract.
Why 2026 changes the math: Open Semantic Interchange and AI execution layers
Two developments are reshaping the portability landscape: the emergence of Open Semantic Interchange as a cross-vendor specification, and the rapid expansion of BI platforms into AI execution layers.
The SBI Group reports that Snowflake convened the Open Semantic Interchange initiative in September 2025 and that an OSI specification was released in January 2026 ↗. The specification is licensed under Apache 2.0 and is intended to describe datasets, relationships, measures, dimensions, and contextual metadata ↗. That is promising, but a GitHub project page lists version 0.2.0-dev0 and a latest released version of 0.1.1, indicating that public version signals are not yet fully consistent across sources ↗.
What does this mean practically? Track OSI as a development worth watching, but do not treat it as an established cross-vendor standard without verifying production support ↗. Ask vendors whether they plan to support OSI import and export, and test any claimed support against your own semantic models.
The AI angle matters because Thoughtworks’ Technology Radar places semantic layers in the context of BI, APIs, and AI agents, indicating that semantic-layer portability is increasingly being evaluated as an architecture issue rather than merely a dashboard feature ↗. If your metric definitions are trapped inside a single BI tool, your AI initiatives inherit that dependency. Portability is no longer just about dashboards; it is about whether your organization’s business knowledge is accessible to whatever system needs it next.
For teams comparing specific platforms, our Power BI vs Tableau comparison applies a similar portability lens to two of the most widely deployed tools.
Contract and procurement levers most buyers forget
The following procurement safeguards are practical recommendations rather than requirements stated in the linked product documentation.
Technical portability means nothing if the contract does not guarantee your right to retrieve your own artifacts.
Make the contract specify customer ownership and retrieval rights for source data, derived data, semantic metadata, audit logs, dashboard definitions, and usage records. A technically documented export function is not equivalent to a contractual right to retrieve every relevant artifact at termination.
Six clauses to consider in a BI procurement contract:
The relevance and wording of each clause depend on the deployment model, jurisdiction, and commercial arrangement. Review them with your procurement and legal advisers.
- Export SLA. The vendor must provide a documented, tested export path for every artifact category within a specified number of days after termination notice.
- Metadata ownership. You own the semantic model definitions, calculated measures, and relationship mappings, not just the raw data.
- API commitments. Require a published API rate limit, authentication model, versioning policy, and deletion procedure before treating an API as a genuine exit mechanism.
- Escrow for deployable custom components. Where the engagement includes customer-specific source code or deployable components, consider whether an escrow arrangement would provide a practical continuity option. Escrow is not a complete exit solution for every SaaS platform.
- Termination for convenience. Without this, you negotiate from weakness.
- Embedded analytics separation. Test embedded analytics separately from internal dashboarding because embedding can create application-level dependencies on vendor SDKs, JavaScript libraries, tokens, and licensing terms.
Use a two-layer procurement scorecard that assigns separate scores to data portability and application portability. Data portability concerns extraction and reuse of records and metadata, whereas application portability concerns rebuilding dashboards, alerts, subscriptions, embedded experiences, permissions, and operational workflows.
SMB vs. enterprise: a different path to the same protections
Small and mid-sized businesses face the same portability risks as enterprises but need a lighter-weight approach to managing them.
An enterprise (250 or more employees) can afford a dedicated data platform team, a formal semantic layer, and a procurement office that negotiates custom contract terms. A small and medium-sized business (SMB, fewer than 250 employees by the EU definition) typically cannot. The protections still apply; they just take a different form.
For an SMB, the highest-leverage move is Test 4 from the framework above: separate transformation logic from the visualization tool. Even a small team using a managed data warehouse and a version-controlled SQL repository gains significant portability. The BI tool becomes a presentation layer that reads from views you control, rather than a monolith that owns your business logic.
On the connectivity side, an SMB should still evaluate whether the tool connects to more than one cloud and on-premises data platform. A tool that only works with one cloud provider’s ecosystem ties two vendor relationships together, compounding switching costs.
| Portability control | SMB emphasis | Enterprise emphasis |
|---|---|---|
| Storage independence | High | High |
| Governed semantic layer | Selective | High |
| Contract safeguards | Essential baseline | Detailed and negotiated |
| Version-controlled transformations | High | High |
This is an editorial decision framework based on organizational complexity, not an empirical benchmark. Both paths lead to the same outcome: a BI stack you can leave without rebuilding from scratch.
For organizations ready to assess where they stand, our BI assessment packages are designed to map these dependencies.
Frequently asked questions about choosing a business intelligence tool
Does using open file formats like Parquet or Delta Lake guarantee portability?
No. Open file formats preserve your data storage, but they do not automatically make a BI deployment portable. Calculations, security semantics, refresh orchestration, and visual layouts may remain trapped in proprietary metadata. Microsoft identifies Delta Lake, Parquet, and Iceberg as open formats in its Power BI documentation, while the existence of an open file format does not guarantee portability of security policies, calculated measures, or dashboard definitions ↗. Test what actually exports, not what the storage layer supports.
If a BI tool has REST APIs, is that enough for an exit plan?
Not automatically. Power BI exposes REST APIs and XMLA-based programmability, but the practical portability of those interfaces depends on tenant permissions, licensing, API quotas, and the availability of equivalent capabilities in the replacement platform ↗. A third common mistake is treating a vendor’s API as a complete exit plan without testing authentication, quotas, version compatibility, and export coverage for every production artifact. Run the export against your actual reports, not a sample workspace.
How do I compare two BI tools on portability without a months-long evaluation?
Run a focused proof of concept. Pick five representative reports: one with row-level security, one with incremental refresh, one with time-intelligence calculations, one embedded dashboard, and one executive report with external distribution. Attempt to export each from the current tool and reconstruct it in the candidate. Measure the effort in person-days. That number tells you more than any feature checklist. Microsoft’s documentation identifies XMLA, REST APIs, TOM, TMDL, and open formats as interoperability mechanisms, but these features do not make every report portable ↗.
Choose the business intelligence tool that makes leaving cheap
The BI market will keep consolidating, AI capabilities will keep expanding, and your organization’s needs will keep shifting. The one constant is this: the tool that costs the least to leave gives you the most negotiating power while you stay.
Every criterion on a typical BI evaluation scorecard (visualization quality, AI features, user experience, price) becomes negotiable when your switching cost is low. When your switching cost is high, the vendor sets the terms.
The five-test framework, the migration-cost worksheet, and the contract clauses outlined above are not theoretical. They are practical instruments you can apply to your next BI procurement or your current renewal. The organizations that use them will spend less time fighting vendor dependencies and more time doing what BI is supposed to enable: making better decisions with trustworthy data.
At Veralytiq, we build dashboards, automations, and AI solutions where the client owns the code, the data, and the systems, with no lock-in to us. That principle shapes how we advise on choosing a business intelligence tool too.
If you want a structured look at where lock-in sits in your current BI stack, a Discovery engagement (current state and gap assessment, quick-win recommendations and a roadmap, typically two to four weeks) is the place to start, ideally before your next renewal.
Independence note: Veralytiq has no commercial relationship with any vendor named in this article.
Related Articles
- Comparing BI Tools: A Complete Guide for Dutch Mid-Market Companies — How the main BI tools compare
- Enterprise Business Intelligence: What Breaks at Scale — How business intelligence works at enterprise scale